Message Queues 101: RabbitMQ, Kafka, Redis
February 20, 2025#backend#messaging#redis
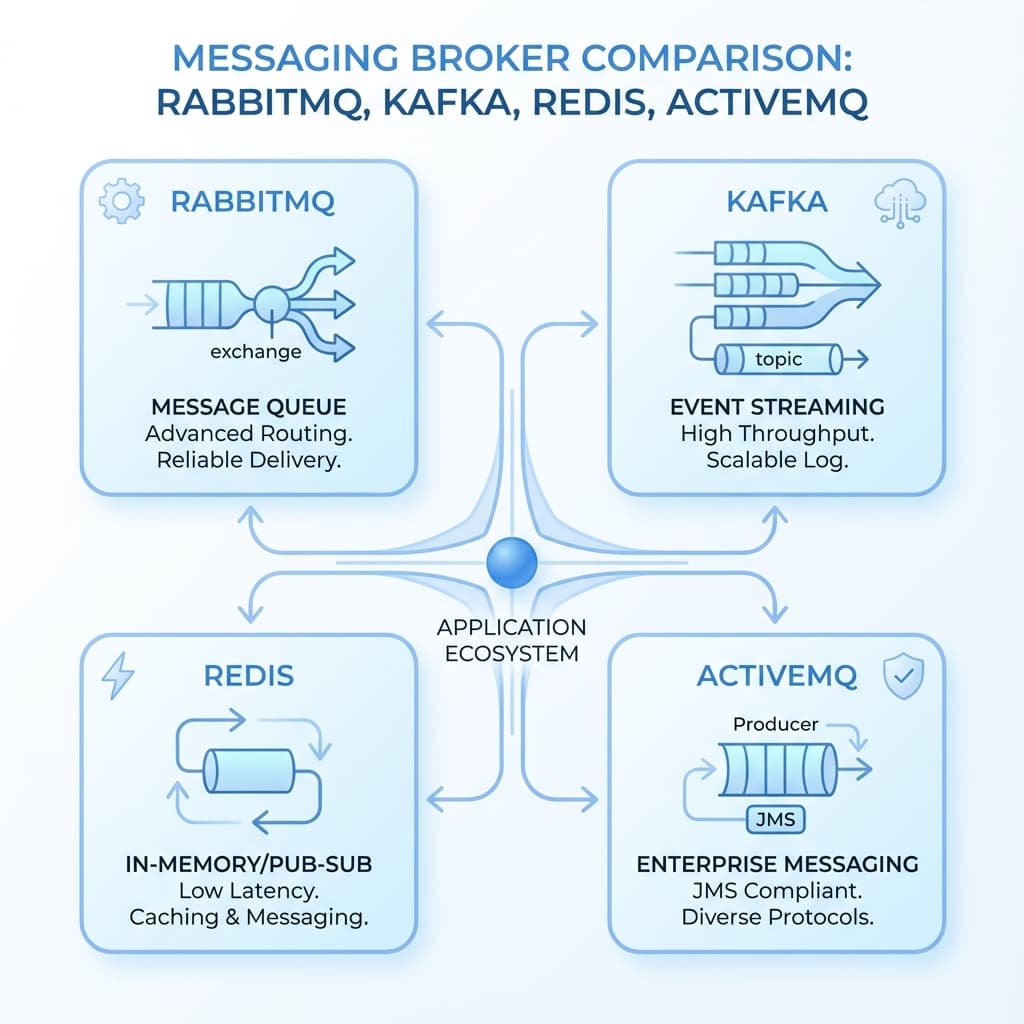
First: the honest question
A queue adds a moving part. Before choosing one, answer: do you need to decouple timing? If the producer and consumer can live in the same request, you do not need a queue — you need a function call.
When you genuinely need one
- The producer is faster than the consumer. Uploads → thumbnails; orders → emails.
- The consumer may fail and you must not lose the work. The "send the receipt" job retries until it succeeds.
- Multiple consumers want the same event. Audit + analytics + notifications, each with its own pace.
What I actually run
Redis pub/sub. Not because it is the most powerful — because it is the least moving parts that still decouples. One process, one data structure, zero protocol.
// publish
await redis.publish('order.placed', JSON.stringify(order));

// subscribe (in a worker)
const sub = redis.duplicate();
await sub.subscribe('order.placed');
sub.on('message', (channel, message) => handleOrder(JSON.parse(message)));
RabbitMQ earns its keep when you need routing and per-queue retries. Kafka earns its keep when you need replay and high throughput at scale — a problem most teams never actually have.
Start with Redis. Move to RabbitMQ when the routing hurts. Move to Kafka when the volume is real. The queue is not the product; the reliability is.
***